CSV Without the Panic: How to Make Computerised System Validation Proportionate, Practical and Useful
When CSV feels harder than it needs to be
The system has been selected.
The supplier says it is validated.
The users want to get started.
IT is focused on implementation.
QA is asking about intended use, data integrity, access control, supplier evidence, testing, change management and lifecycle control.
The project team is already under pressure.
Then someone says:
“We need to validate it.”
That is often the point where confidence starts to drop.
Computerised System Validation, or CSV, can feel intimidating even for experienced organisations. It sits between technology, quality, operations, vendors, users and regulatory expectations. It involves systems, processes, data, documentation, risk, supplier evidence and human behaviour.
It can quickly become unclear who owns what.
IT may understand the technical implementation but not the regulated use.
QA may understand validation expectations but not the system detail.
Users may understand the process but not the evidence required.
The supplier may provide documentation, but not always in a way that fits the organisation’s intended use.
Leadership may simply want the system live, safe and compliant without unnecessary delay.
In that environment, CSV can become either overcomplicated or under-controlled.
Some organisations create large documentation packs that nobody finds useful after approval.
Others rely too heavily on supplier claims and assume that because a system is widely used, it must be acceptable.
Neither extreme is ideal.
CSV should not be a panic exercise.
It should be a structured way of answering a practical question:
“Can we be confident that this system is fit for its intended regulated use, and that risks to data, quality and decision-making are appropriately controlled?”
That is the centre of good CSV.
Not templates.
Not document volume.
Not copying what another organisation did.
Confidence in intended use.
CSV is not about proving that a system exists
A common problem with CSV is that organisations treat it as a documentation requirement rather than a confidence-building process.
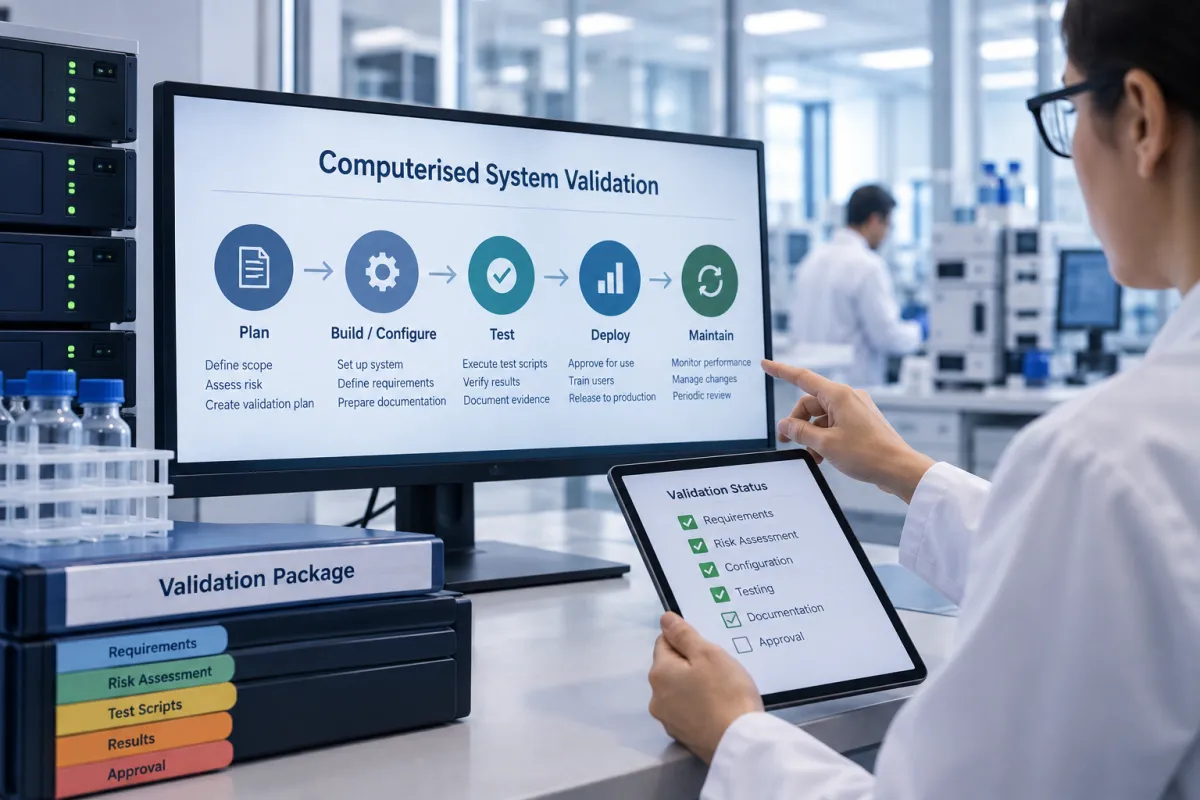
They focus on producing the validation plan, user requirements, risk assessment, test scripts, traceability matrix, summary report and supporting records.
Those documents may be necessary.
But documents are not the purpose of CSV.
The purpose is to demonstrate that the system can reliably support the process it is being used for, in the context of the organisation’s regulated work.
That means the starting point should not be:
“What documents do we need?”
It should be:
“What do we need this system to do, and what could go wrong if it does not do it properly?”
That question changes the entire tone of the work.
A system used to store non-critical reference information does not create the same risk as a system used to manage clinical trial data, GLP study records, electronic signatures, audit trails, sample tracking, training records, deviations, CAPA, vendor oversight or regulated decisions.
A cloud-based system with strong supplier controls still needs assessment against your organisation’s intended use.
A configurable platform may behave differently depending on how it is set up.
A spreadsheet used in a critical process may create significant data integrity risk despite appearing simple.
A system may be technically functional but still poorly controlled if access, roles, data flow, change management or user training are weak.
CSV is therefore not just a technical exercise.
It is a quality and business confidence exercise.
It asks whether the system, as used by your organisation, supports reliable work.
Why CSV becomes painful
CSV usually becomes painful for one of several reasons.
Intended use is unclear
This is probably the most common cause.
If nobody has clearly defined what the system will be used for, validation becomes vague. Requirements become generic. Testing becomes unfocused. Risk assessment becomes difficult. Supplier documentation is accepted or rejected without a clear basis.
The organisation ends up validating a system in the abstract.
But systems are not used in the abstract.
They are used for specific processes, by specific people, to create, process, review, approve, store, transfer or report specific information.
Good CSV starts with intended use.
What process will the system support?
What records or data will it create or manage?
What decisions will rely on it?
What regulatory expectations apply?
What could go wrong?
What would the impact be?
Without that clarity, CSV becomes documentation theatre.
Ownership is split or vague
CSV often falls between functions.
IT owns the technology.
QA owns the quality expectations.
Operations owns the process.
Users own the day-to-day work.
The supplier owns some of the technical evidence.
Leadership owns the decision to invest and implement.
If ownership is not defined clearly, validation work slows down. Questions bounce between teams. Decisions are delayed. Documents are written by people who do not fully understand the process. QA is involved late and then appears to be holding up progress.
A system does not become controlled because one department says it is.
It becomes controlled because the right people understand their roles across the system lifecycle.
Supplier documentation is misunderstood
Supplier evidence can be extremely useful.
It can reduce duplication, support risk-based validation and help the organisation avoid unnecessary testing.
But supplier documentation is not a substitute for understanding your own use of the system.
A supplier may provide test evidence, certifications, technical controls, security documentation, release notes, validation packages or quality statements. These can all support validation decisions.
But the organisation still needs to ask:
Does this evidence apply to our intended use?
Does it cover our configuration?
Does it address the regulated functions we rely on?
What remains our responsibility?
What assumptions are we making?
What gaps need to be addressed internally?
The danger is not using supplier evidence.
The danger is accepting it without interpretation.
Risk assessment happens too late
Risk assessment should guide the validation approach.
Too often, it is completed after major decisions have already been made.
The system has been bought. The configuration is mostly set. Documentation expectations are assumed. Testing has been planned. Then risk is assessed to justify what is already happening.
That weakens the value of risk-based validation.
A useful risk assessment helps decide where effort is needed.
Which functions are critical?
Which data need protection?
Where could errors affect study integrity, patient safety, product quality, regulatory confidence or business decisions?
Which controls are manual, technical or procedural?
Which supplier evidence can be relied upon?
Where does the organisation need additional testing or review?
Risk should shape the work, not decorate it.
Templates drive the process
Templates are useful when they support good thinking.
They are not useful when they become the process.
Many organisations inherit CSV templates from larger companies, previous employers, consultants or historical validation approaches. The templates may be technically sound, but they may not fit the system, the risk or the maturity of the organisation.
The result can be excessive documentation, duplicated content, unclear purpose and frustration for everyone involved.
A template should help people capture the right rationale.
It should not force a small organisation into an oversized approach or make a low-risk system look more complex than it is.
CSV is treated as a one-off event
Validation is often seen as something that happens before go-live.
That is only part of the story.
A system can be validated at implementation and become uncontrolled later if change management, access review, supplier updates, incident management, backup, training, periodic review or data retention are weak.
CSV is not only about getting the system approved.
It is about maintaining confidence throughout the system lifecycle.
That does not mean constant revalidation. It means appropriate lifecycle control.
What proportionate CSV looks like
Proportionate CSV is not “light CSV”.
It is not doing the minimum.
It is doing the right work for the risk, intended use and context.
For a lower-risk system, proportionate validation may be relatively simple. The organisation still needs to understand intended use, assess risk, confirm suitability, define controls and maintain evidence, but the level of testing and documentation may be modest.
For a critical system, proportionate validation may be more detailed. The organisation may need stronger requirements, deeper supplier assessment, more robust testing, clearer traceability, defined access controls, data integrity assessment and more formal lifecycle review.
The principle is the same.
Validation effort should match risk.
That risk should be based on what the system does, how it is used, what records or data it controls, what decisions rely on it, and what the impact would be if it failed or produced unreliable information.
Proportionate CSV is practical because it avoids two common mistakes.
It avoids under-control, where the organisation relies on assumptions and supplier claims without enough evidence.
It also avoids over-control, where excessive documentation creates cost and delay without improving confidence.
Good CSV should make the organisation more confident.
Not simply more documented.
A practical CSV confidence framework
Before starting validation activity, it is useful to work through a simple confidence framework.
CSV area | Key question | Why it matters |
|---|---|---|
Intended use | What will the system actually be used for? | Defines the scope and relevance of validation |
Process fit | How does the system support the regulated process? | Prevents validating technology without understanding work |
Data and records | What data or records does the system create, process, store or report? | Identifies data integrity and reconstruction risks |
Users and roles | Who will use the system, and what access do they need? | Supports access control, segregation and training |
Supplier evidence | What evidence can we rely on, and what are its limits? | Avoids unnecessary duplication and blind reliance |
Configuration | How has the system been set up for our use? | Ensures validation reflects the actual system |
Risk | What could go wrong, and what would the impact be? | Guides effort and control selection |
Testing | What evidence do we need to show the system works as required? | Keeps testing focused and meaningful |
Change control | How will changes be assessed after go-live? | Maintains confidence through the lifecycle |
Ownership | Who owns the system, process, data and ongoing review? | Prevents post-implementation drift |
This framework is not a replacement for a validation procedure.
It is a way to keep the work grounded.
If the validation documentation answers these questions clearly, the organisation is more likely to have useful evidence rather than a large file of disconnected documents.
What organisations often do instead
When CSV feels difficult, organisations tend to move in one of two directions.
Some underreact.
They accept the supplier’s statement that the system is validated. They assume that because other companies use the system, it must be acceptable. They treat the system as an IT implementation rather than a regulated process control. They do not fully assess intended use, configuration, data integrity, access, change or lifecycle responsibilities.
This can feel efficient until an audit, inspection, system issue or data question exposes the gaps.
Others overreact.
They create a validation package far larger than the system justifies. They test functions the organisation does not use. They duplicate supplier testing without rationale. They complete forms because the template asks for them. They generate traceability that nobody uses. They create documentation volume but not necessarily better control.
This can feel safe, but it drains time, frustrates users and reinforces the idea that CSV is bureaucratic.
Both patterns come from the same root problem.
The organisation has not clearly defined what confidence should look like.
Once that is clear, CSV becomes easier to scale.
The role of QA, IT, users and suppliers
CSV works best when the right people contribute the right expertise.
QA should not be expected to validate a system alone.
IT should not be expected to interpret all regulated process risks alone.
Users should not be expected to produce validation evidence without support.
Suppliers should not be expected to understand every detail of the organisation’s regulated use.
Each party has a role.
QA helps define quality expectations, risk interpretation, documentation standards, supplier assessment and evidence requirements.
IT helps with technical implementation, infrastructure, security, access, integrations, support and system management.
Users explain how the process works, what the system needs to do, where errors could occur, and what would make the system fit for purpose.
Suppliers provide technical information, system documentation, testing evidence, security details, release management information and support arrangements.
Leadership ensures the right people are involved early enough, decisions are made, and the organisation does not treat validation as an afterthought.
When these roles are unclear, CSV becomes slow and frustrating.
When they are clear, validation becomes a shared exercise in building confidence.
CSV and the problem of “the supplier says it’s validated”
This phrase appears often.
“The supplier says the system is validated.”
It may be true from the supplier’s perspective. But supplier validation does not automatically validate your use of the system.
The supplier may have tested the platform.
They may have a quality management system.
They may perform release testing.
They may provide documentation for customers.
They may have security and availability controls.
That is valuable.
But your organisation still needs to understand how the system will be used in your regulated process.
For example:
Which functions will you use?
How will roles and permissions be configured?
What data will be entered, changed, reviewed or approved?
What audit trail functionality matters?
What reports will support decisions?
How will electronic signatures be used, if applicable?
How will changes be assessed?
How will users be trained?
How will issues be managed?
What happens if the system is unavailable?
What records need to be retained?
The supplier can support these questions.
It cannot answer all of them for you.
Your organisation owns intended use.
That is why supplier evidence should be assessed, not merely filed.
CSV as a business issue, not just a compliance issue
CSV is often positioned as a compliance requirement.
It is that, but it is also more than that.
A poorly controlled system can create business risk.
It can delay implementation.
It can make users lose confidence.
It can lead to inefficient workarounds.
It can create unreliable data.
It can undermine inspection readiness.
It can make process ownership unclear.
It can create dependency on a supplier or one internal expert.
It can generate rework when gaps are identified late.
It can damage the credibility of decisions based on system data.
For clinical sponsors, systems may support trial management, TMF, data review, safety reporting, vendor oversight, sample tracking or participant-facing processes.
For preclinical organisations, systems may support study data, raw data handling, laboratory records, equipment, training, deviations, CAPA, document control or reporting.
For quality teams, systems may support the evidence that the organisation uses to show control.
If the system is not fit for purpose, the issue is not only validation.
It is confidence in the work the system supports.
That is why CSV should be connected to business performance, not treated as a technical hurdle.
Questions to ask before validating a system
Before starting validation documentation, ask these practical questions.
1. What regulated process will this system support?
Be specific.
A system is not validated because it has a name, brand or supplier validation pack. It is validated in relation to what your organisation uses it to do.
2. What decisions, records or data depend on it?
This helps clarify impact.
If the system supports critical decisions, regulated records, safety information, study data, quality events or inspection evidence, validation expectations are likely to be higher.
3. Who owns the process, the system and the data?
These may not be the same person.
Clarifying ownership early prevents gaps after implementation.
4. What supplier evidence is available, and how reliable is it?
Supplier evidence can reduce internal effort, but only if it is assessed against your intended use and risk.
5. What could go wrong?
Think practically.
Could data be lost, changed, misreported, accessed inappropriately, approved incorrectly, transferred inaccurately or misunderstood?
Could users bypass the system?
Could configuration changes affect regulated functions?
Could reports be relied upon without verification?
6. What evidence would give us confidence?
This is the central validation question.
The answer should drive documentation, testing and review.
7. How will we maintain control after go-live?
Validation does not end when the system is approved.
Consider change control, periodic review, access review, training, supplier updates, incidents, backup, recovery and retirement.
When external CSV support helps
External CSV support can be valuable when the organisation lacks experience, when the system is high-risk, or when ownership is unclear.
It can also help when internal teams are anxious because they do not know whether their approach is too light, too heavy or simply misdirected.
Good CSV support should not just produce documents.
It should help the organisation think clearly.
That might include:
clarifying intended use;
assessing system and process risk;
reviewing supplier documentation;
defining a proportionate validation strategy;
helping QA, IT and users understand their roles;
identifying what evidence is genuinely needed;
supporting testing and traceability where appropriate;
advising on data integrity and audit trail expectations;
strengthening lifecycle controls;
helping the organisation avoid unnecessary documentation burden.
The right support should leave the organisation with more than an approved validation package.
It should leave people clearer about how the system is controlled, who owns what, and how confidence will be maintained.
This is particularly important for smaller and mid-sized organisations that may not need a large internal CSV function but do need experienced judgement.
It is also important for clinical and preclinical organisations using modern cloud-based systems, supplier-hosted platforms, configurable tools, spreadsheets or specialist applications that support regulated work.
What better looks like
A strong CSV approach feels proportionate and understandable.
The organisation can explain what the system is used for.
It can show why the validation approach fits the risk.
It understands what supplier evidence covers and what it does not.
Users understand their role.
Access is controlled.
Data integrity risks have been considered.
Testing is focused on what matters.
Requirements reflect actual use.
Documentation supports decisions rather than overwhelming them.
Change control maintains confidence after go-live.
The system owner knows what needs to happen next.
QA, IT and operations are not working in separate worlds.
When asked why the organisation is confident in the system, the answer is clear.
Not because the supplier said it was validated.
Not because the template was completed.
Not because the validation file is thick.
But because the organisation understood intended use, assessed risk, gathered relevant evidence, tested what mattered and defined how control would be maintained.
That is CSV without the panic.
The bottom line
Computerised System Validation does not need to be intimidating.
It becomes difficult when organisations start with documents instead of intended use, templates instead of risk, supplier claims instead of assessed evidence, and go-live pressure instead of lifecycle control.
The purpose of CSV is not to create paperwork.
The purpose is to build and demonstrate confidence that a system is fit for its intended regulated use, and that risks to data, quality, compliance and decision-making are controlled.
Sometimes that requires detailed validation work.
Sometimes a simpler, risk-based approach is appropriate.
The answer depends on the system, the process, the data, the users, the supplier evidence and the consequences of failure.
Good CSV is proportionate.
It is practical.
It is evidence-based.
It helps the organisation use systems with more confidence.
What to do next
If CSV in your organisation feels unclear, overcomplicated or anxiety-inducing, it may be worth stepping back before producing more documentation.
The useful question is not:
“What validation documents do we need?”
It is:
“What would give us confidence that this system is fit for its intended regulated use?”
Headway Quality Evolution helps pharmaceutical R&D and GxP-regulated organisations take a practical, proportionate approach to CSV.
That may involve CSV strategy, risk assessment, supplier documentation review, validation planning, user requirement support, testing rationale, data integrity considerations, lifecycle controls or helping QA, IT and operational teams work together more effectively.
The aim is not to make CSV bigger than it needs to be.
The aim is to make it clearer, more useful and better connected to the way your organisation actually works.